Chatbot Integration With Shopify: Complete Beginner’s Guide for 2026
Adding a chatbot to your Shopify store takes 1-3 hours and costs…
Technical deep dives, engineering insights, and architectural discussions from our AI development team. Learn how we build scalable AI systems.
Technical exploration of our microservices architecture that enables AI agents to handle millions of conversations simultaneously.
Explore our collection of thought-provoking discussions
Adding a chatbot to your Shopify store takes 1-3 hours and costs…
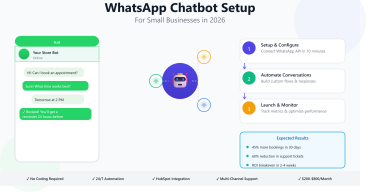
Setting up a WhatsApp chatbot for your small business takes 2-4 hours…
You don't need to be a software developer to build a functional,…
How we implemented circuit breaker patterns to ensure high availability and graceful…
Step-by-step guide to fine-tuning LLMs for specific industries, including data preparation, training…
Security considerations and implementation details for serving multiple clients on shared AI…
Deep dive into our Redis-based state management system that maintains conversation context…
How we achieved 40% faster response times by optimizing our NLP pipeline…
Connect with our engineering team, contribute to open source projects, and stay updated with the latest AI development insights.
Our microservices architecture enables AI agents to handle millions of conversations simultaneously by distributing workload across multiple specialized services. Each service is designed for specific functions like natural language processing, context management, and response generation.
The system uses event-driven communication patterns with Apache Kafka for real-time message streaming, ensuring low latency and high throughput. Load balancing is handled through Kubernetes with auto-scaling policies based on CPU and memory metrics.
We achieved 40% faster response times by implementing custom transformer models with efficient tokenization strategies. Our optimization pipeline includes model quantization, dynamic batching, and caching mechanisms for frequently used patterns.
The key breakthrough came from implementing pipeline parallelization where tokenization, embedding generation, and model inference happen concurrently rather than sequentially.
Our Redis-based state management system maintains conversation context across distributed AI agents using a hybrid approach of in-memory caching and persistent storage. Each conversation maintains a rolling window of context with intelligent pruning algorithms.
State synchronization across multiple agent instances is handled through Redis Streams, ensuring consistency while maintaining sub-millisecond access times.
Security in multi-tenant AI infrastructure requires isolation at multiple levels: data, compute, and network. We implement tenant-specific encryption keys, isolated compute namespaces, and strict API access controls with rate limiting per tenant.
Data isolation is enforced through encrypted database partitioning and tenant-specific AI model instances, ensuring complete separation of sensitive information.
Fine-tuning LLMs for specific industries requires careful data preparation, custom training strategies, and domain-specific evaluation metrics. Our approach includes transfer learning techniques and parameter-efficient fine-tuning methods.
We use LoRA (Low-Rank Adaptation) and QLoRA techniques to fine-tune models efficiently while maintaining base model performance on general tasks.
Circuit breaker patterns ensure high availability and graceful degradation in our AI service APIs. When services experience high error rates or latency, circuit breakers prevent cascade failures by temporarily blocking requests.
Our implementation includes configurable thresholds, exponential backoff strategies, and automatic recovery mechanisms with health checks.
Hi! 👋 How can we help you today?
Start Chat